
Dataset
A multimodal hybrid dataset for validating perception systems in rare, safety‑critical, and underrepresented driving scenarios
Dataset
A multimodal hybrid dataset for validating perception systems in rare, safety‑critical, and underrepresented driving scenarios
The just better DATAset is a multimodal dataset designed to support robust validation and analysis of perception systems in safety‑critical driving scenarios. The dataset has been curated with a strong focus on underrepresented, rare, and safety‑relevant situations, addressing known gaps in conventional real‑world driving data.
Dataset Overview
The dataset consists of three data batches, each collected using three independent test vehicles from the following project partners:
- AVL Deutschland GmbH (AVL)
- b-plus technologies GmbH (b-plus)
- FZI Forschungszentrum Informatik (FZI)
equipped with heterogeneous multimodal sensor setups, including:
- LiDAR
- Radar
- Camera
This setup enables comprehensive multimodal perception research and provides realistic sensor diversity reflective of real‑world deployments.
The metadata for the real-world data is provided as ASAM OpenLABEL files. This also enables the seamless use of the various data batches thanks to a standardized description format.
- Meta data as ASAM OpenLABEL
Focus on Safety‑Critical and Long‑Tail Scenarios
Unlike generic driving datasets, the jbDATAset explicitly targets challenging and safety‑critical scenarios, including but not limited to:
- Unknown or uncommon objects on the road
- Diverse and adverse weather conditions
- Situations that are typically underrepresented in large‑scale fleet data
This makes the dataset particularly well‑suited for validation, robustness testing, and failure analysis of perception models.
Hybrid Real & Synthetic Data Design
In order to further improve the distribution of the real-world data, the dataset adopts a hybrid strategy and supplements the jbDATAset with purpose-built synthetic data:
- Synthetic Data Batch from AUMOVIO
The synthetic components are not intended to replace real data, but to systematically complement it, enabling controlled variation, improved coverage of rare scenarios, and targeted stress testing. This hybrid approach is especially valuable for model validation and generalization assessment.
Ground Truth and Pseudolabels
To support different stages of development and evaluation, the dataset provides:
- High‑quality ground truth annotations for selected samples
- Pseudolabels for other parts of the dataset
This reflects realistic industrial workflows and allows users to study:
- Model performance under varying label fidelity
- The impact of pseudolabeling in validation and benchmarking pipelines
- Strategies for combining ground truth and weak supervision
Intended Use
The jbDATAset is designed primarily for:
- Validation and robustness evaluation
- Safety‑oriented perception research
- Analysis of long‑tail and rare scenarios
- Benchmarking multimodal perception systems
- Research on hybrid real‑synthetic data strategies
It is not intended as a generic training dataset, but as a high‑value asset for testing, analysis and validation, particularly in safety‑critical contexts.
Publication
The consortium of just better DATA will publish and present a paper about the jbDATAset within the Curated Data for Efficient Learning Workshop at the ECCV 2026 in Malmö (September 8 – 12th, 2026). Once the paper is published it will be linked here.
Key Information about the data batches
| AVL | B-PLUS | FZI | |
| NUMBER of SEQUENCES | 148 | 572 | 500 |
| LENGTH of SEQUENCES | 20 sec | 10 sec | 20 sec |
| DATA SIZE | ~0.97TiB | 2.0TiB | ~1.7TiB |
| DATA TYPES | - Camera images - LiDAR pointclouds | - Camera images - LiDAR pointclouds - Radar pointclouds | - Camera images - LiDAR pointclouds - Radar pointclouds |
| ANNO-TATIONS | - 3D Bounding Boxes (Detection 9Hz, Tracking 5Hz, LiDAR) - 2D Bounding Boxes (6Hz, Front Camera) | none | - 3D bounding boxes (2 Hz, human annotated) - 3D LiDAR semantic segmentation (2 Hz, human annotated) - 2D bounding boxes (2 Hz, pseudolabels, front camera) |
| WEATHER | - Sun - Rain - Snow | - Sun - Rain - Fog | - Sun - Rain |
| ROADTYPES | - Urban - Rural - Highway | - Urban - Rural - Highway | - Urban - Rural - Highway |
| TRIGGERS | - Criticality detection - Anomaly Detection (unusual acceleration behaviour of Ego Vehicle) | none | none |
Preview of the data batches
AVL Dynamic Ground Truth (DGT) is a highly precise reference measurement system for automated and connected driving. It was developed to operate as an independent, objective environmental reference for sensor evaluation. The modular roof-mounted system is equipped with 3 lidar sensors, 6 cameras, and a dGPS (differential GPS) device for centimeter-precision dynamic positioning.
The dataset was recorded on a variety of scenes, including complex traffic situations, targeted operational design domains. The recorded dataset provides 3D LiDAR detections and tracking alongside 2D object detections from the front-facing camera, with every tenth annotated with 2D Bounding Boxes.


The b-plus research vehicle “NOVA” was developed as part of the jbDATA project and specifically designed to meet its requirements. It features a multimodal sensor suite comprising cameras, LiDAR, and radar. The sensors are arranged to closely resemble the configuration found in production vehicles. In addition, the setup is complemented by reference sensors.
The dataset was primarily collected in eastern Bavaria and includes urban, rural, and highway scenarios. Recordings were conducted across multiple seasons to capture a wide range of weather conditions, including heavy snow, rain, and fog, as well as varying lighting conditions.


The FZI data batch of the jbDATAset consists of 500 20-second scenes selected from the larger FZI-AURA dataset and was recorded using the CoCar NextGen, a multi-purpose research platform for automated and connected driving.
The Audi A6 Avant plug-in hybrid is equipped with 12 state-of-the-art LiDAR sensors, 3 radars and 9 cameras, as well as a Car2X onboard unit and a high-precision IMU with dual-antenna GNSS. The published dataset contains data from 8 synchronized surround-view cameras, up to 12 LiDAR sensors, and up to 3 radar sensors.
The dataset was recorded in a variety of scenes, including urban, rural, and highway driving in various weather conditions. Human-annotated 3D bounding boxes and LiDAR semantic segmentation are provided at 2 Hz. In addition, 2D bounding-box pseudolabels for one front-facing camera are provided at 2 Hz.


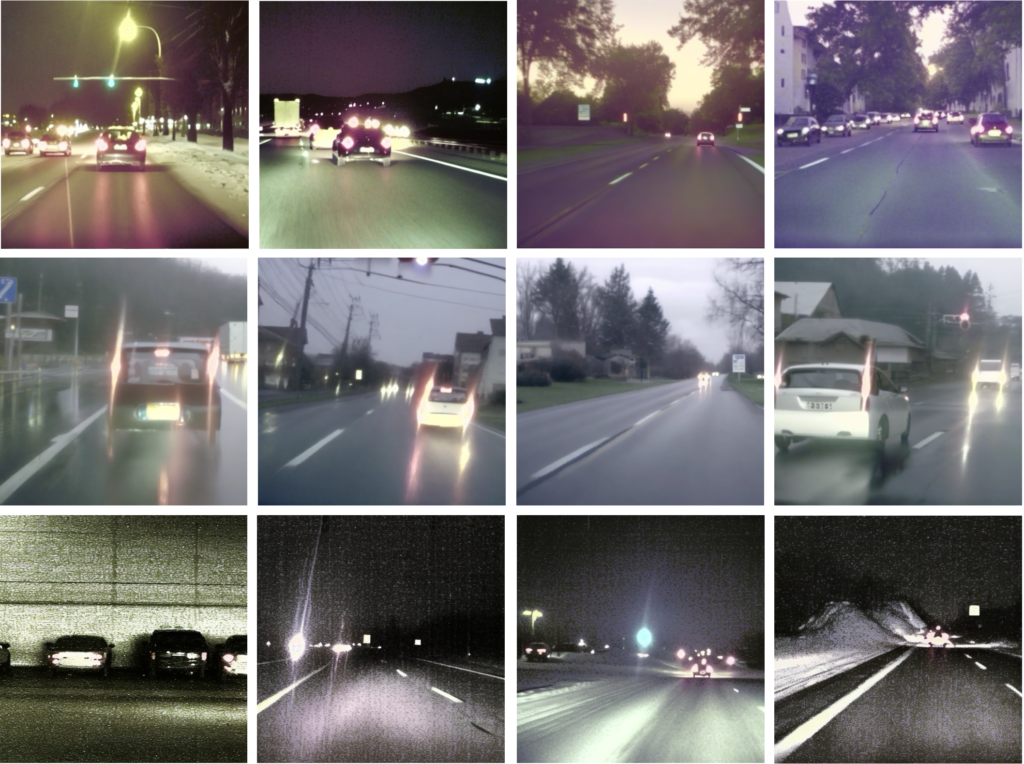
The jbDATA Synthetic Dataset contains 10,000 automatically annotated synthetic driving images generated to complement real-world sensor recordings with scenarios that are difficult to acquire and balance through conventional data collection alone. Developed within the jbDATA Smart Data Loop framework, the dataset targets underrepresented operating conditions relevant to autonomous driving, with a particular focus on adverse weather, including rain and snow, challenging illumination, nighttime scenes, tunnels, and other situations that can impact perception performance and robustness. The synthetic data was created as part of a targeted data-enrichment process guided by coverage and data-gap analysis, supporting the development and evaluation of AI systems under challenging environmental conditions. The release is provided in the widely adopted MS COCO format with object-level annotations, enabling straightforward integration into existing computer vision validation and benchmarking workflows.
The following picture shows some examples of the AUMOVIO synthetic dataset:
Download
The OpenLABEL data download contains metadata for the three real-world datasets from AVL, b-plus and FZI.
Clicking the button will take you to the corresponding web space.
Please note that the data batches are published under the following license: CC-BY-SA 4.0.
Please refer to the respective partner’s download page for more information and the correct citation of the data batches.
The best way to download the full dataset including the OpenLabel files is to first download the OpenLABEL repository and then download the raw data into the corresponding subfolder of the partner inside the jbDATAset folder. The resulting folder structure should look like this:
jbDATAset
├── openlabel
│ ├── avl/
│ │ ├── sequence_00001.json # any name that corresponds to the sequence
│ │ ├── sequence_00002.json
│ │ └── …
│ ├── b-plus/
│ └── fzi/
├── avl # the raw data folder for the AVL subset
├── b-plus # the raw data folder for the bplus subset
└── fzi # the raw data folder for the FZI subset